Agent Reliability Review
Find out in 4 weeks whether your AI agent is ready for production.
A fixed $12,500 review of one agent stuck in pilot. Day 5 brings the first failure list, by week 3 a test suite built from your traces runs in your CI, and week 4 ends in a written go or no-go with every fix estimated.
Day 5
First failure list
Week 3
Test suite in your CI
Week 4
Go or no-go memo
3
Live production systems
The adoption gap
The adoption gap is operational.
Models are improving quickly. The hard part is selecting the right workflow, integrating it with real systems, governing its actions, and earning sustained user trust.
327%
growth in multi-agent workflows in less than four months on Databricks.
19%
of audited organizations had deployed agents at scale, according to report coverage.
12x
more AI projects reached production among organizations using AI governance.
Market evidence: Databricks, 2026 State of AI Agents (20,000+ organizations; 327% and 12x findings); SiliconANGLE coverage (19% at scale). Databricks telemetry reflects its customer base and is not statistically projectable to all enterprises.
The Agent Reliability Review
$12,500, fixed. One agent, one workflow, 4 weeks.
For an agent that works in demos while nobody can say how often it fails on real traffic, or why. You walk into the next leadership review with a number and a decision.
- Day 5
The first failure list
Modeo reads your first 50 traces and names where the agent fails, with a count for each failure mode.
- Week 3
The suite runs in your CI
Every failure mode reproduced as a runnable test, built from up to 200 of your traces, running in your own pipeline.
- Week 4
The go or no-go
A pass rate, the failure taxonomy, and a 2-page decision memo with every fix estimated. You keep the suite.
- Who it is for
- The VP of Engineering or head of AI at a US company of 200 to 2,000 people, with an agent in pilot
- Not a fit yet
- No agent yet: start with the AI Opportunity Assessment. Healthcare data under HIPAA is not in scope
- Scope
- One agent, one workflow, up to 200 traces or transcripts
- You provide
- Read access to traces, a 45-minute kickoff, two 30-minute reviews
- Included
- A re-run 30 days after your fixes; $3,750 credited to a build signed within 30 days
- Payment
- 50% on signature, 50% on delivery. Delivered whatever the verdict
How we work
Review, build, then hand over a system your team owns.
Each step ends with a decision you make on measured results. On handoff you own the system, the evaluation suite, and the runbook. The retainer is optional.
- 01
Agent Reliability Review
Test one agent stuck in pilot on your own traces and decide, in writing, whether it goes to production. No agent yet? The AI Opportunity Assessment ($7,500, 2 to 3 weeks) picks the workflow first.
- Day 5: the first failure list
- Week 3: a test suite running in your CI
- Week 4: a go or no-go with every fix estimated
- A re-run 30 days after your fixes
4 weeks · $12,500 · $3,750 credited to a build signed within 30 days
- 02
Production Build
Build the fixes or the workflow into your stack, from the existing pilot or from zero, and hand it to your team.
- Real users on live traffic
- Automated tests on every change
- Human-in-the-loop controls
- A named owner with the runbook
From $28,000, quoted after a Review or Assessment · final 20% on production acceptance
- 03
Monitor and Improve
Optional after handover: up to 27.5 hours a month in business hours to keep the system healthy. A second agent starts as a new Review.
- Monitoring and alert review
- The suite re-run on every model or prompt change
- Monthly cost report
- One change of up to 10 hours a month
Optional · $5,500 a month
What we measure
Success is defined before the build starts and reported against a baseline.
Adoption
Active users, repeat use, workflow completion
Business ROI
Cycle time, cost, quality, revenue impact
Operational trust
Accuracy, escalation, auditability, reliability
Capability transfer
Client ownership, training, reusable patterns
Selected Work
Systems we designed, built, and shipped
Three production systems, the business workflows each pattern fits, and what a Reliability Review tests on each.
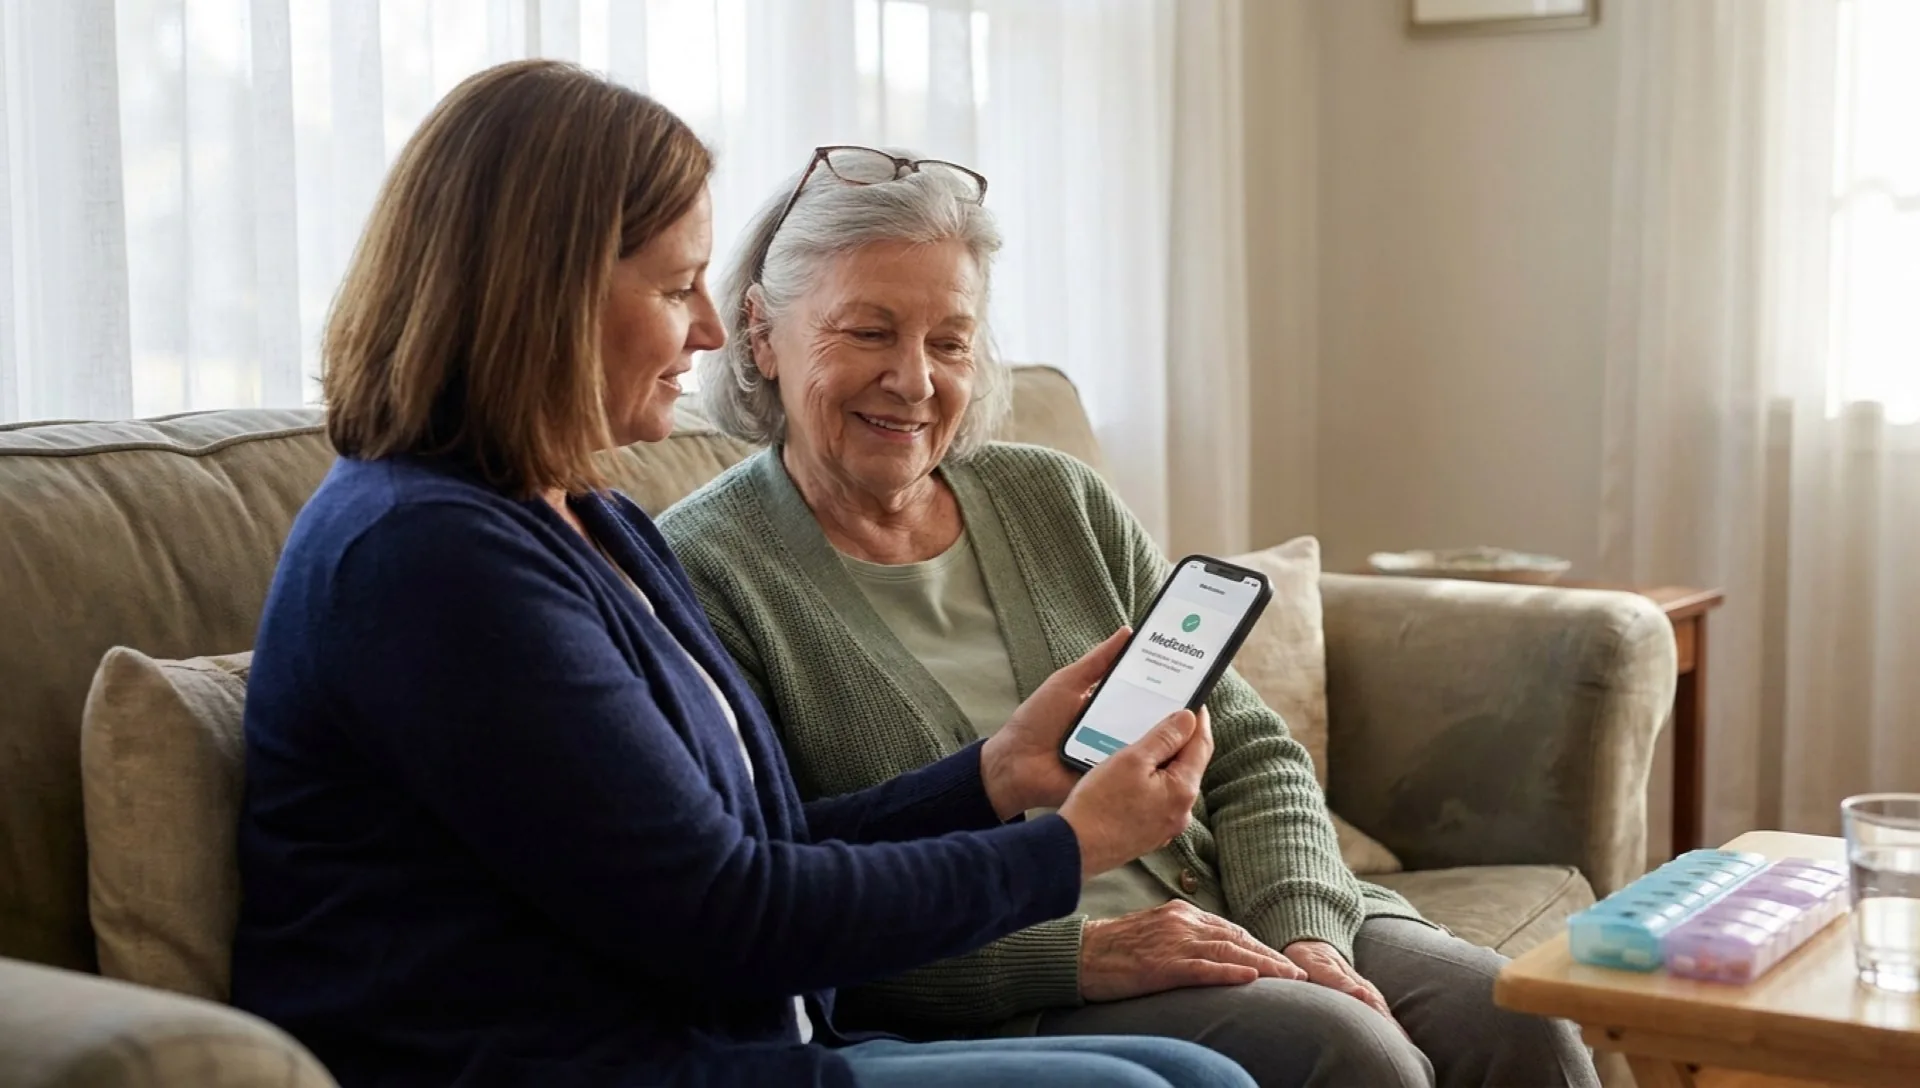
Conversational AI · Healthcare
FamilyCheck
Pattern: an outbound voice agent that gets consent, looks up the caller's own records mid-call, and logs a structured outcome for a human.
Modeo designed, built, and operates FamilyCheck: consent-gated daily medication check-in calls, retrieval over each patient's medications, real-time tool use, and caregiver notifications on a Vapi, Twilio, and Resend stack.
Where the pattern applies
- Appointment confirmation and rescheduling calls
- Insurance renewal and missing-document calls
- Delivery and service-window confirmation
- Post-visit and post-service check-in calls
What a Reliability Review tests on a system like this
- Does every reported concern reach the caregiver with the symptom named?
- Are medical-advice and off-topic requests declined and logged with the right status?
- Does the agent stay calm and avoid emergency language when the patient is not in danger?
- Is anything private or internal ever spoken aloud?
Verified analysis · Financial data
Daily Macro Briefing
Pattern: scheduled data pulls, a rules engine that makes the call, one constrained language model that writes it up, and a validator that checks every number before it publishes.
Modeo built and operates this: a pipeline that pulls 26 indicators from public sources twice a day, then has one constrained language model write the briefing, with every number machine-checked against the source.
Where the pattern applies
- Client portfolio commentary in wealth management
- Monthly variance commentary in management reporting
- KPI and operations briefings
- Board and investor update drafts
What a Reliability Review tests on a system like this
- Does every number in the text match its source value?
- Does a failed validation fall back cleanly instead of publishing?
- Does an implausible source value stop the model from running?
- Do duplicate or delayed runs publish exactly once?
Analysis without a language model · Real estate
FlipFinder.
Pattern: a deterministic scoring engine that pulls records, applies written rules, and ranks every item the same way every time, with no language model.
Modeo built FlipFinder end to end, from the underwriting model to the live web app: a deterministic engine that scores listings on flip and rental economics against comparable sales.
Where the pattern applies
- Loan and credit pre-screening
- Insurance pre-quote rating
- Supplier bid scoring
- Property and asset valuation
What a Reliability Review tests on a system like this
- Does the same input always produce the same score?
- Does every estimate state its source and a confidence rating?
- Do thin or missing comparables lower the confidence?
- Can any data source produce an implausible profit?
Why Modeo
Proof from three live production systems Modeo built
No single model or cloud vendor is required. You keep the system, the evaluation suite, and the runbook.
Shipped to production
FamilyCheck is a live, autonomous voice agent we built and operate, not a demo or a slide.
Consent-first & governed
Auditable consent flows, guardrails, evals, and human-in-the-loop controls built in from day one.
Works in your stack
Shipped systems run OpenAI and Google models, Vapi, Twilio, and Cloudflare. The stack for your workflow follows your existing contracts and governance.
FamilyCheck
Daily check-in calls for the people you love.
FamilyCheck is your family's AI-powered medication companion. We call your loved ones daily with a warm, friendly voice, and keep you informed every step of the way.
For enterprises: under the hood, FamilyCheck is a fully autonomous voice agent Modeo designed, built, and operates in production: consent-gated outbound calls, retrieval over each patient's medications, real-time tool use, and multi-channel notifications on a Vapi, Twilio, and Resend stack. It's living proof we ship safe, regulated agentic systems end to end.
Medication confirmed
George took his Metformin · 9:02 AM
Sent to you via WhatsApp
FamilyCheck calling George
Example call · 0:14
Hi George! This is Anna from FamilyCheck, calling on behalf of your family. How are you feeling today?
Oh, hello! I'm doing well, thank you.
I'm just calling to check on your Metformin. Have you had a chance to take it today?
Yes, I took it with breakfast this morning.
That's wonderful, George! You're taking such great care of yourself. I'll let your family know. They love you so very much. Have a beautiful day!
An illustrative transcript: how a FamilyCheck morning call sounds.
A warm human voice
Friendly daily calls that sound like a caring family friend, never a robot.
Instant caregiver updates
Know the outcome of every call via WhatsApp or email, in seconds.
Works on any phone
No app, no smartphone, no internet. They just answer and talk.
Read the FamilyCheck build case study
How it works
Tell us about your loved one
Their name, medications, dosages and preferred call times. That's it.
We get their consent
FamilyCheck calls the patient first, so reminders only begin once they agree.
Daily check-in calls
A warm AI voice reminds them at exactly the right times, every day.
You stay informed
Real-time updates land in your WhatsApp or inbox after every single call.
Built for families like yours
Three illustrative caregivers, drawn from the situations FamilyCheck is designed for.
Sarah
Long-distance daughter
“Lives three states away from her dad. FamilyCheck calls him every morning so she never has to wonder whether he remembered his heart medication.”
Mike
Sandwich-generation son
“Juggles his kids, his job and his mother's care. FamilyCheck handles the daily medication checks so he can focus on being present.”
The Rodriguez Family
Shared caregiving
“Four siblings share the caregiving. FamilyCheck keeps everyone informed with real-time updates after every call.”
Who We Are
Technology Meets Human Ingenuity
Modeo is a founder-led AI product studio. Arash Yazdani builds the products he designs. He shipped FamilyCheck end to end: a production GenAI voice agent with an eval-driven prompt loop, verbal-consent gating, and fail-closed reliability. He also leads Modeo's agentic engagements across investment, software, real estate, and legal. Over 11 years in product management he has delivered consumer and enterprise AI for organizations including UCLA Health, AEG/Coachella, Porsche, and Target.
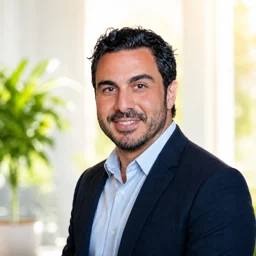
Arash Yazdani
Founder & CEO
Builds, not just advises. Shipped FamilyCheck solo (~18K LOC; Vapi, GPT-4o, ElevenLabs) with eval-driven prompts, consent gating, and fail-closed webhook verification across Vapi, Twilio, and Stripe.
Agentic delivery across industries. Leads Modeo's hands-on agent builds in investment (macroeconomic insight), software (multi-agent PRD), real estate (leads-finder + CRM), and legal (case intake).
Enterprise scale. 11 years in product management, delivering SLA-governed programs for organizations including UCLA Health, AEG/Coachella, Porsche, Target, and MLS, including a real-time media pipeline behind 100M+ annual brand impressions across Coachella and 25 global festivals.
0→1 product builder. Launched ROEME, a 4.9★ App Store social scheduling and payments app, and REC.US Technologies, a municipal recreation marketplace scaled to thousands of users. MBA (Pepperdine) and AI Product Management certified.
Client-Focused
Your success is our mission. We embed ourselves in your challenges to deliver outcomes that matter.
Innovation-Driven
We embrace emerging technologies and bold ideas to keep you ahead of the curve.
Human + Machine
We combine human ingenuity with AI capabilities to unlock unprecedented value.
Real Impact
Building products that solve meaningful problems for families and businesses.
FAQ
Enterprise agentic AI, answered
Common questions from teams evaluating, building, and deploying AI agents.
Who can help get an AI agent out of pilot and into production?+
Modeo's Agent Reliability Review takes one AI agent stuck in pilot to a production decision: $12,500, fixed, 4 weeks, one agent, one workflow, up to 200 traces. It delivers a failure list on day 5, a test suite built from your traces running in your CI by week 3, and a written go or no-go in week 4 with every fix estimated. A go verdict leads to a Production Build, from $28,000 and quoted after the Review.
Do you offer a fractional AI product manager for an AI agent pilot?+
Not as a separate service; the Agent Reliability Review covers the product decisions a fractional AI product manager would own on an agent pilot: what the agent fails at, which failures block production, what each fix costs, and whether to ship. It is $12,500, fixed, 4 weeks, for one agent and one workflow, run by Arash Yazdani, Founder & CEO.
Who does AI voice agent evaluation and testing?+
Modeo does, through the Agent Reliability Review: $12,500, fixed, 4 weeks, for one voice agent and one workflow, ending in a test suite built from your call traces running in your CI and a written go or no-go. Modeo built and tests its own voice agent, FamilyCheck, which is in private beta with its first consented patient; its 53-scenario adversarial test suite is scored by a judge model validated in a single-rater blinded agreement study.
How do you deploy AI agents securely in an enterprise?+
We design agents with least-privilege access, guardrails, evaluation, and human-in-the-loop controls, integrate them into your existing security and identity stack, and roll out through controlled pilots before scaling.
How do you govern and evaluate agents in production?+
Every agent ships with evals, observability, and policy guardrails. We track task success, cost, and safety, and keep humans in the loop for high-stakes actions, so you can trust what the agent does.
Can you work within regulated industries like healthcare and finance?+
Financial data, yes: under a mutual NDA, and inside your environment when your policy requires it. Healthcare data covered by HIPAA is not in scope until Modeo's vendor business associate agreements are confirmed. FamilyCheck, Modeo's own voice agent, shows the consent-first design Modeo would use.
What does an engagement look like?+
It starts with an Agent Reliability Review: $12,500, fixed, 4 weeks, for one agent and one workflow. Day 5 brings the first failure list, week 3 the test suite running in your CI, and week 4 a written go or no-go with every fix estimated. A go verdict leads to a Production Build, from $28,000 and quoted after the Review. Teams with no agent yet start with an AI Opportunity Assessment ($7,500, 2 to 3 weeks). $3,750 of either fee is credited to a build signed within 30 days. Monitor and Improve ($5,500 a month) is optional after handover.
Can't our team build evals ourselves?+
It can. The Review delivers a suite built from your own traces and running in your CI within 4 weeks, at a fixed $12,500, and your team keeps it. Two engineers spending 20 hours a week on it for a month cost about $32,000 at a $200 hourly contract rate.
Is a founder-led firm a delivery risk?+
Scope is capped at one agent and one workflow for that reason, and every deliverable stays with your team: the test suite runs in your CI, and the test code and decision memo are yours.
Our traces contain customer data. How does the Review handle it?+
A mutual NDA comes first. Modeo works from redacted traces, or inside your environment on access you grant.
Is Modeo tied to a model or cloud vendor?+
No single model or cloud vendor is required. Our shipped systems run OpenAI and Google models, Vapi and Twilio for voice, and Cloudflare for delivery; the stack for your workflow follows your existing contracts, latency, and governance needs.
Get in Touch
Start with the agent stuck in pilot.
Bring one agent and one workflow. In 4 weeks you have a pass rate on your own traces, a test suite in your CI, and a written go or no-go.
Recommended first step
A 30-minute call on where your agent stands and whether a Reliability Review fits. Prefer email? Write to [email protected] instead.
Book a review callNo meeting yet? Request a written proposalBuilt with leading technology